A majority element is one that appears more than nums.length / 2 times.
Algorithm Proceeding-
First, choose a candidate from the given set of elements
if it is the same as the candidate element, increase the votes. Otherwise,
decrease the votes if votes become 0, select another new element as the new candidate.
public static int findMajorityElement(int[] nums) {
        int majorityElement = 0;
        int count = 0;

        for (int num : nums) {
            if (count == 0) {
                majorityElement = num;
                count = 1;
            } else if (num == majorityElement) {
                count++;
            } else {
                count--;
            }
        }
}
Kadane’s Algo
Kadane’s algorithm a popular dynamic programming algorithm, it is used for finding the maximum sum of a contiguous subarray in an array. it efficiently handles both positive and negative numbers.
Conditions/Cases to remember
does it handle empty array?[NA]
does it handle all -ve element, i.e what will be the ans in this case, since sum of 2 -ve is grater -ve number. [YES]
should we consider using 0 or arr[i] as substitution in code – Any works ,but corresponding initiation & iteration required.
It works by maintaining two variables:maxSoFar & maxEndingHere
maxSoFar stores the maximum sum of any contiguous subarray seen so far, and
maxEndingHere stores the maximum sum of any contiguous subarray ending at the current index.
public static int maxSubArraySum(int[] nums) {
int maxSoFar=Integer.MIN_VALUE;//final result initiated to min not 0, for cases where elements with -ve numbers would result in max being 0 -which is incorrect.
        int maxEndingHere=0;
        for(int i=0;i<nums.length;i++){
            maxEndingHere=Math.max(nums[i]+maxEndingHere,nums[i]);
            maxSoFar=Math.max(maxSoFar,maxEndingHere);
        }
      return maxSoFar;
}
Selection Sort is best when memory write operations are costly since it makes the minimum possible number of swaps compared to other two.
Insertion Sort is preferable for small or nearly sorted data.
Bubble Sort is typically used for educational purposes to demonstrate sorting techniques but is rarely used in practical applications due to its inefficiency.
Selection Sorting
Algorithm :
Iterate through the array to find the smallest (or largest) element.
Swap the found minimum (or maximum) element with the first element.
Move the boundary of the unsorted subarray by one element.
Repeat the process for the remaining unsorted portion of the array.
  private static void selectionSort(int[] arr) {
        int n = arr.length;
        for (int i = 0; i < n; i++) {
            int minIndex = i;
            for (int j = i + 1; j < n; j++) {
                if (arr[j] < arr[minIndex]) {
                    minIndex = j;
                }
            }
//optimisation used :  outer loop used for swapping - internal for index tracking
            int temp = arr[minIndex];
            arr[minIndex] = arr[i];
            arr[i] = temp;

        }
    }
Time Complexity: O(n²)
Space Complexity: O(1) (In-place sorting)
Bubble Sort
Algorithm :
Compare adjacent elements in the array.
Swap them if they are in the wrong order.
Continue doing this for each pair of adjacent elements until the array is fully sorted
.After each pass, the next largest element is in its correct position.
Repeat the process until no swaps are needed (the array is sorted).
  private static void bubbleSort(int[] arr) {
        int n = arr.length;
        for (int i = 0; i < n - 1; i++) {

            for (int j = 0; j < n - 1; j++) {
                if(arr[j]>arr[j+1]){
                    int temp=arr[j+1];
                    arr[j+1]=arr[j];
                    arr[j]=temp;
                }
            }
        }

    }
Time Complexity: O(n²)
Space Complexity: O(1) (In-place sorting)
Insertion Sort
Algorithm :
Start from the second element, assume that the first element is already sorted.
Pick the next element and compare it with the elements in the sorted part.
Shift all elements in the sorted part that are greater than the current element to the right.
Insert the current element into its correct position.
Repeat the process until the entire array is sorted.
 public static void insertionSort(int[] arr) {
        int n = arr.length;
        for (int i = 1; i < n; i++) {
            int key = arr[i];
            int j = i - 1;
            // Move elements of arr[0..i-1] that are greater than key to one position ahead
            while (j >= 0 && arr[j] > key) {
                arr[j + 1] = arr[j];
                j = j - 1;
            }
            arr[j + 1] = key;
        }
    }
Time Complexity: O(n²)
Space Complexity: O(1) (In-place sorting)
Quick Sort
Algorithm :
Choose a “pivot” element from the array.
Partition the array into two sub-arrays: elements less than the pivot and elements greater than the pivot.
Recursively apply the same steps to the sub-arrays.
Combine the sub-arrays to get the sorted array.
  public static void quickSort(int[] arr, int low, int high) {
        if (low < high) {
            int pi = partition(arr, low, high);
            quickSort(arr, low, pi - 1);  // Recursively sort elements before partition
            quickSort(arr, pi + 1, high); // Recursively sort elements after partition
        }
    }

    private static int partition(int[] arr, int low, int high) {
        int pivot = arr[high];
        int i = (low - 1); // Index of smaller element
        for (int j = low; j < high; j++) {
            if (arr[j] < pivot) {
                i++;
                // Swap arr[i] and arr[j]
                int temp = arr[i];
                arr[i] = arr[j];
                arr[j] = temp;
            }
        }
        // Swap arr[i+1] and arr[high] (or pivot)
        int temp = arr[i + 1];
        arr[i + 1] = arr[high];
        arr[high] = temp;

        return i + 1;
    }
Time Complexity:
Best Case: O(n log n)
Worst Case: O(n²) (occurs when the smallest or largest element is always chosen as the pivot)
Space Complexity: O(log n) (in-place sorting, though recursion stack takes
Merge Sort
Algorithm :
Divide the array into two halves.
Recursively sort each half.
Merge the two halves to create a sorted array.
public class MergeSort {
    public static void mergeSort(int[] arr, int left, int right) {
        if (left < right) {
            int middle = (left + right) / 2;
            // Sort first and second halves
            mergeSort(arr, left, middle);
            mergeSort(arr, middle + 1, right);
            // Merge the sorted halves
            merge(arr, left, middle, right);
        }
    }

    private static void merge(int[] arr, int left, int middle, int right) {
        int n1 = middle - left + 1;
        int n2 = right - middle;

        // Temporary arrays
        int[] L = new int[n1];
        int[] R = new int[n2];

        // Copy data to temp arrays
        for (int i = 0; i < n1; i++)
            L[i] = arr[left + i];
        for (int j = 0; j < n2; j++)
            R[j] = arr[middle + 1 + j];

        // Merge the temp arrays
        int i = 0, j = 0;
        int k = left;
        while (i < n1 && j < n2) {
            if (L[i] <= R[j]) {
                arr[k] = L[i];
                i++;
            } else {
                arr[k] = R[j];
                j++;
            }
            k++;
        }

        // Copy remaining elements of L[]
        while (i < n1) {
            arr[k] = L[i];
            i++;
            k++;
        }

        // Copy remaining elements of R[]
        while (j < n2) {
            arr[k] = R[j];
            j++;
            k++;
        }
    }

    public static void main(String[] args) {
        int[] arr = {12, 11, 13, 5, 6, 7};

        // Call mergeSort with the full range of the array
        mergeSort(arr, 0, arr.length - 1);

        // Print the sorted array
        System.out.println("Sorted array:");
        for (int num : arr) {
            System.out.print(num + " ");
        }
    }
}
Dynamic Programming (DP) is a programming paradigm that can systematically and efficiently explore all possible solutions to a problem. As such, it is capable of solving a wide variety of problems that often have the following characteristics:
The problem can be broken down into “overlapping subproblems” – smaller versions of the original problem that are re-used multiple times.
The problem has an “optimal substructure” – an optimal solution can be formed from optimal solutions to the overlapping subproblems of the original problem.
Fibonacci Example –
If you wanted to find the n^{th}nth Fibonacci number F(n)F(n), you can break it down into smaller subproblems – find F(n – 1)F(n−1) and F(n – 2)F(n−2) instead. Then, adding the solutions to these subproblems together gives the answer to the original question, F(n – 1) + F(n – 2) = F(n)F(n−1)+F(n−2)=F(n), which means the problem has optimal substructure, since a solution F(n)F(n) to the original problem can be formed from the solutions to the subproblems. These subproblems are also overlapping – for example, we would need F(4)F(4) to calculate both F(5)F(5) and F(6)F(6).
These attributes may seem familiar to you. Greedy problems have optimal substructure, but not overlapping subproblems. Divide and conquer algorithms break a problem into subproblems, but these subproblems are not overlapping (which is why DP and divide and conquer are commonly mistaken for one another).
There are two ways to implement a DP algorithm:
Bottom-up, also known as tabulation.
Top-down, also known as memoization.
Bottom-up (Tabulation)
Bottom-up is implemented with iteration and starts at the base cases. Let’s use the Fibonacci sequence as an example again. The base cases for the Fibonacci sequence are F(0)=0 and F(1) = 1. With bottom-up, we would use these base cases to calculate F(2)F(2), and then use that result to calculate F(3), and so on all the way up to F(n)
Pseudi COde
// Pseudocode example for bottom-up

F = array of length (n + 1)
F[0] = 0
F[1] = 1
for i from 2 to n:
    F[i] = F[i - 1] + F[i - 2]
Top-down (Memoization)
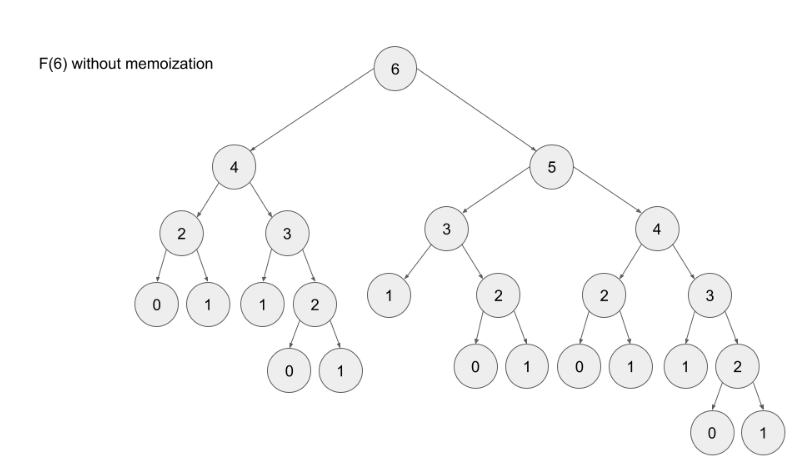
Top-down is implemented with recursion and made efficient with memoization. If we wanted to find the n^{th}nth Fibonacci number F(n)F(n), we try to compute this by finding F(n – 1)F(n−1) and F(n – 2)F(n−2). This defines a recursive pattern that will continue on until we reach the base cases F(0) = F(1) = 1F(0)=F(1)=1. The problem with just implementing it recursively is that there is a ton of unnecessary repeated computation. Take a look at the recursion tree if we were to find F(5)F(5):
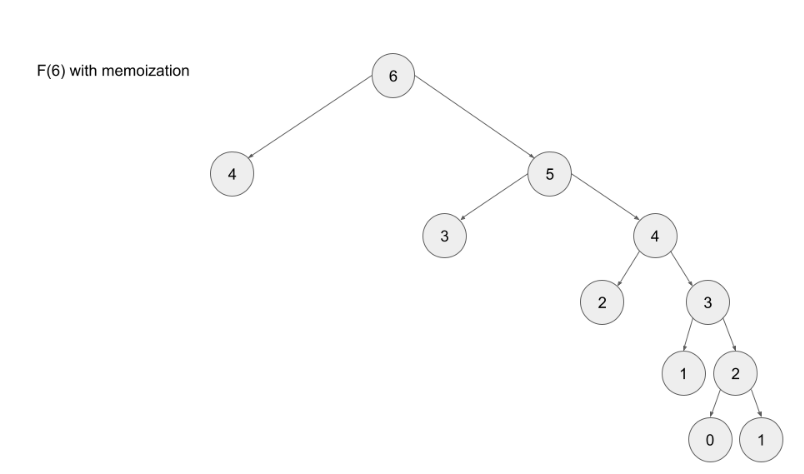
Notice that we need to calculate F(2) three times. This might not seem like a big deal, but if we were to calculate F(6), this entire image would be only one child of the root. Imagine if we wanted to find F(100) – the amount of computation is exponential and will quickly explode. The solution to this is to memoize results.
Note- memoizing a result means to store the result of a function call, usually in a hashmap or an array, so that when the same function call is made again, we can simply return the memoized result instead of recalculating the result.
memorisation vs without memorisation
Advantages
It is very easy to understand and implement.
It solves the subproblems only when it is required.
It is easy to debug.
Disadvantages
It uses the recursion technique that occupies more memory in the call stack.
Sometimes when the recursion is too deep, the stack overflow condition will occur.
It occupies more memory that degrades the overall performance.
When to Use DP
Following are the scenarios to use DP-
The problem can be broken down into “overlapping subproblems” – smaller versions of the original problem that are re-used multiple times
The problem has an “optimal substructure” – an optimal solution can be formed from optimal solutions to the overlapping subproblems of the original problem.
Unfortunately, it is hard to identify when a problem fits into these definitions. Instead, let’s discuss some common characteristics of DP problems that are easy to identify.
The first characteristic that is common in DP problems is that the problem will ask for the optimum value (maximum or minimum) of something, or the number of ways there are to do something. For example:
Optimization problems.
What is the minimum cost of doing…
What is the maximum profit from…
How many ways are there to do…
What is the longest possible…
Is it possible to reach a certain point…
Combinatorial problems.
given a number N, you’ve to find the number of different ways to write it as the sum of 1, 3 and 4.
Note: Not all DP problems follow this format, and not all problems that follow these formats should be solved using DP. However, these formats are very common for DP problems and are generally a hint that you should consider using dynamic programming.
When it comes to identifying if a problem should be solved with DP, this first characteristic is not sufficient. Sometimes, a problem in this format (asking for the max/min/longest etc.) is meant to be solved with a greedy algorithm. The next characteristic will help us determine whether a problem should be solved using a greedy algorithm or dynamic programming.
The second characteristic that is common in DP problems is that future “decisions” depend on earlier decisions. Deciding to do something at one step may affect the ability to do something in a later step. This characteristic is what makes a greedy algorithm invalid for a DP problem – we need to factor in results from previous decisions.
Algorithm –
You can either use Map or array to store/memoize the elements (both gives O(1) access time.